CARouter Blog
What we measured, what we changed, who we work with, and why - written by the people running the gateway, with the numbers and the clauses.
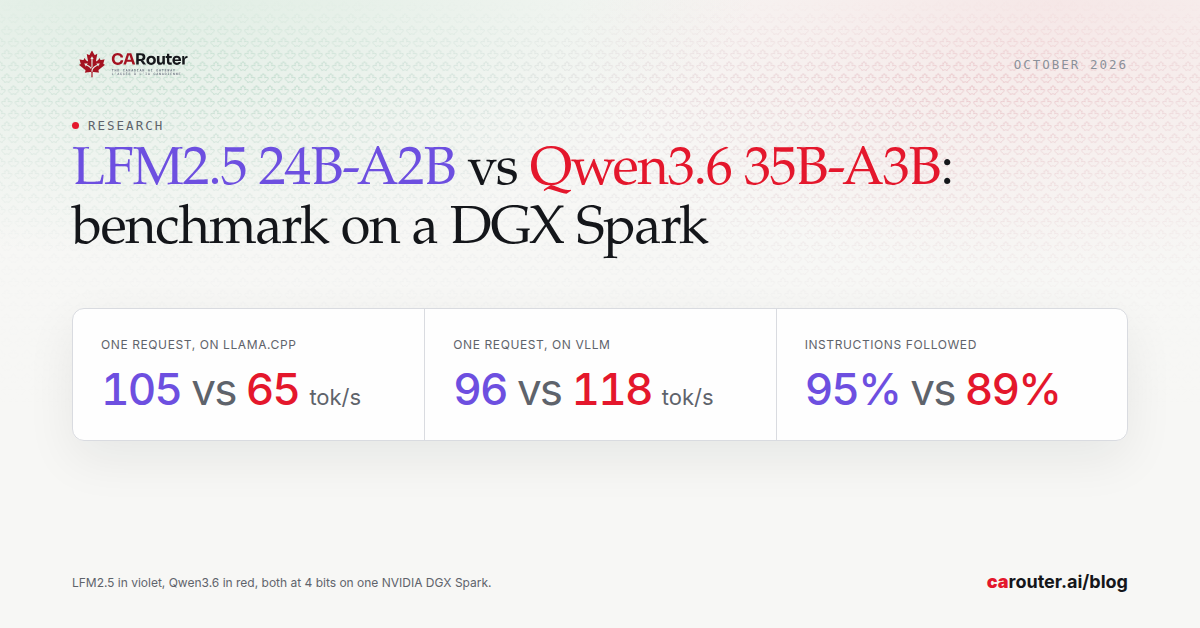
LFM2.5 24B-A2B vs Qwen3.6 35B-A3B: benchmark on a DGX Spark
Liquid AI says its new LFM2.5 24B-A2B is faster than the Qwen3.6 35B-A3B we serve. On a DGX Spark that holds on llama.cpp, 105 tokens a…
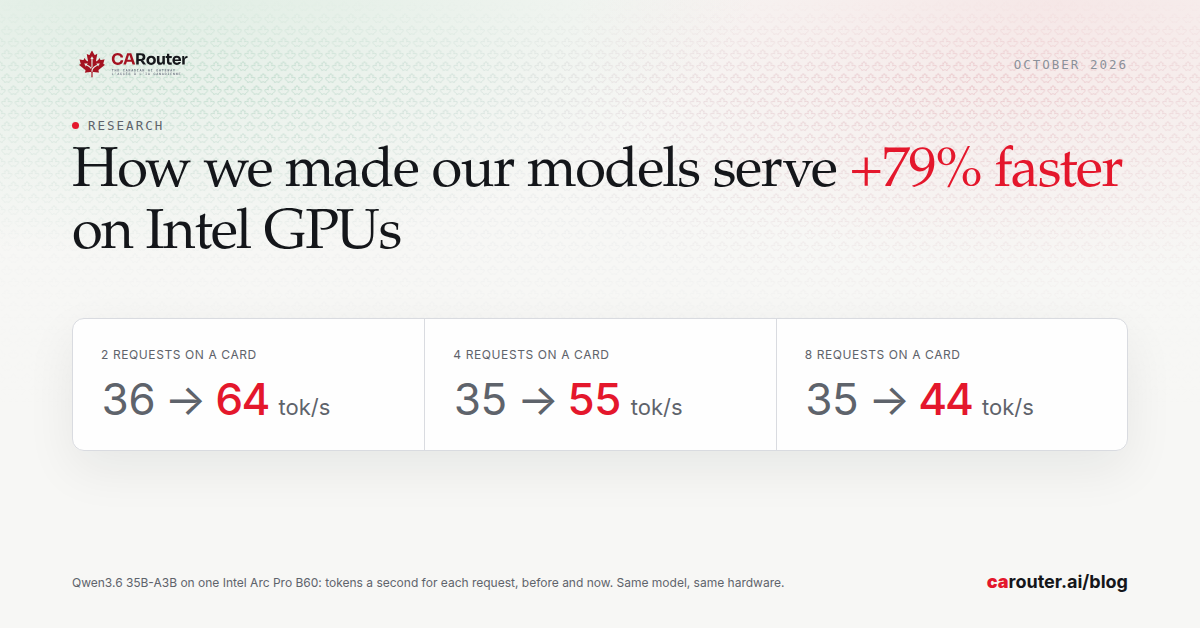
Read the articleHow we made our models serve +79% faster on Intel GPUs
Our two Intel Arc Pro B60 cards serve Qwen3.6 35B-A3B. Most of each step was being spent in Python on the server's processor, not on the…
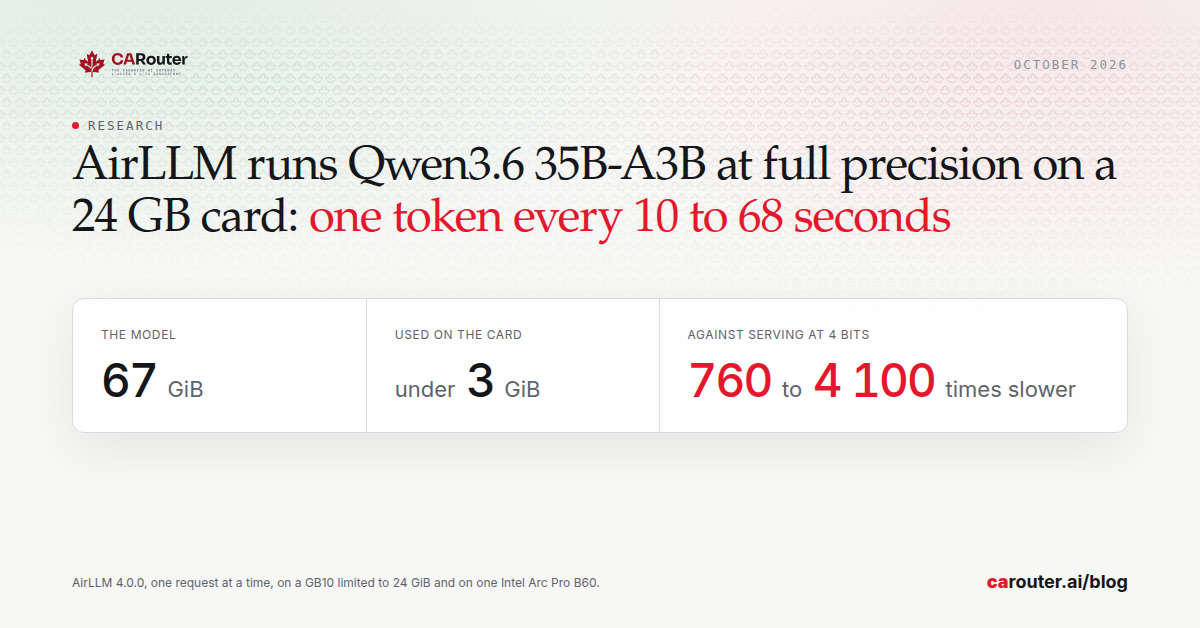
Read the articleAirLLM runs Qwen3.6 35B-A3B at full precision on a 24 GB card: one token every 10 to 68 seconds
AirLLM is an open-source library that passes a model through a graphics card one layer at a time. With it, Qwen3.6 35B-A3B at full…
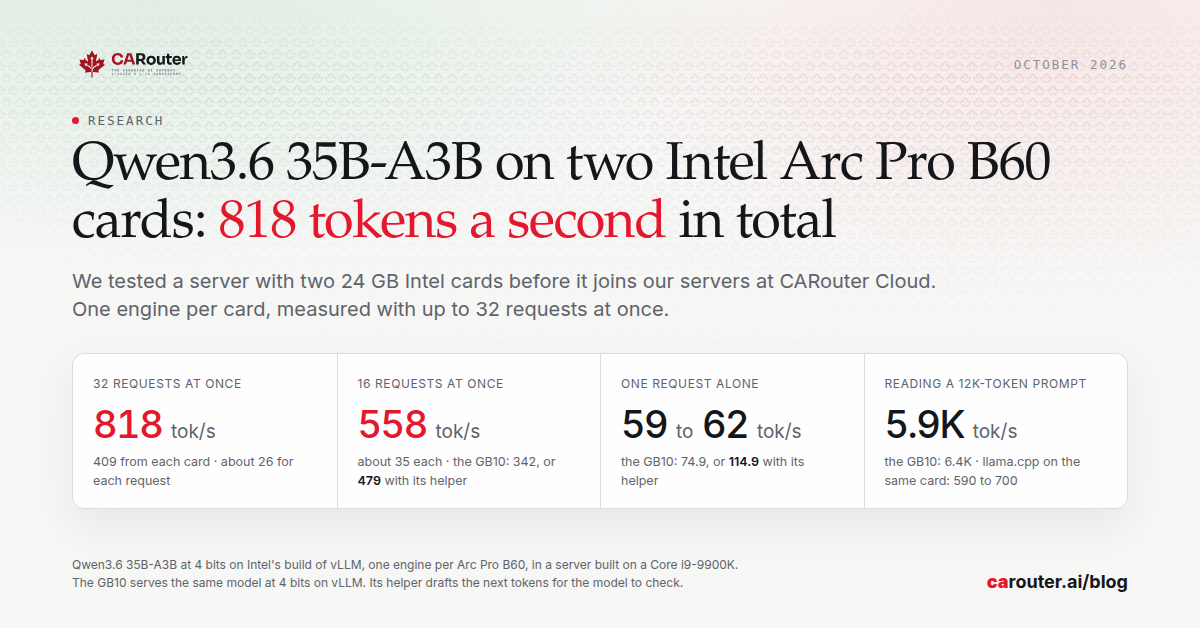
Read the articleQwen3.6 35B-A3B on two Intel Arc Pro B60 cards: 818 tokens a second in total
We tested a server with two Intel Arc Pro B60 cards. Running Qwen3.6 35B-A3B at 4 bits with one engine per card, it writes 818 tokens a…
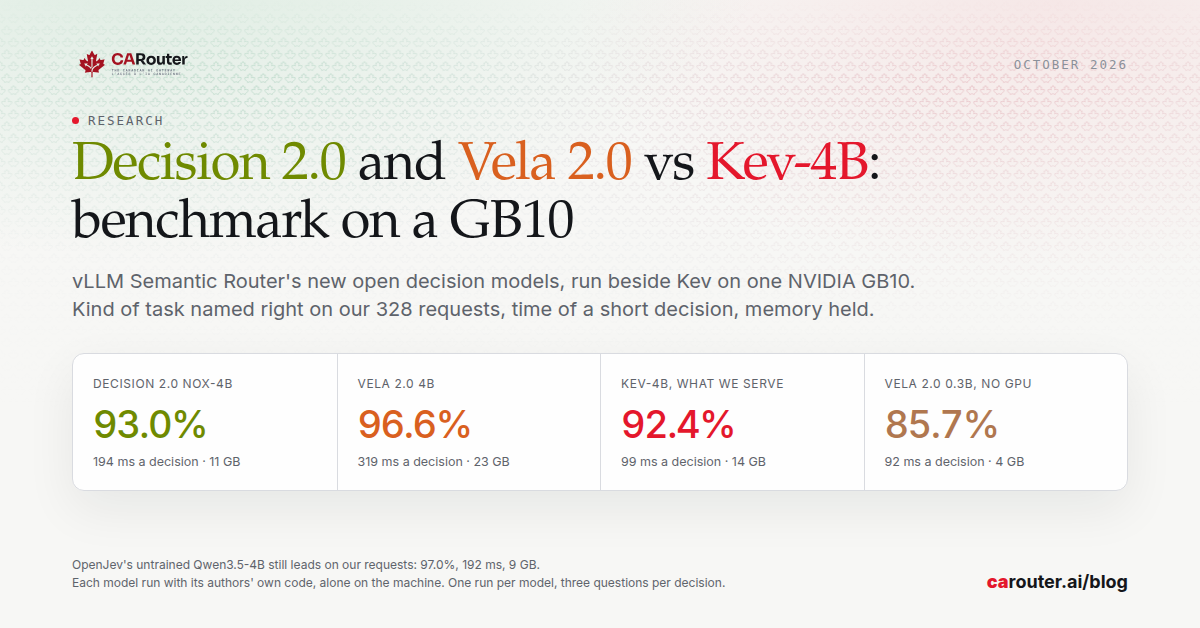
Read the articleDecision 2.0 and Vela 2.0 vs Kev-4B: benchmark on a GB10
vLLM Semantic Router has released two families of open decision models, Decision 2.0 and Vela 2.0. On a GB10, Vela 2.0 4B named the kind of…
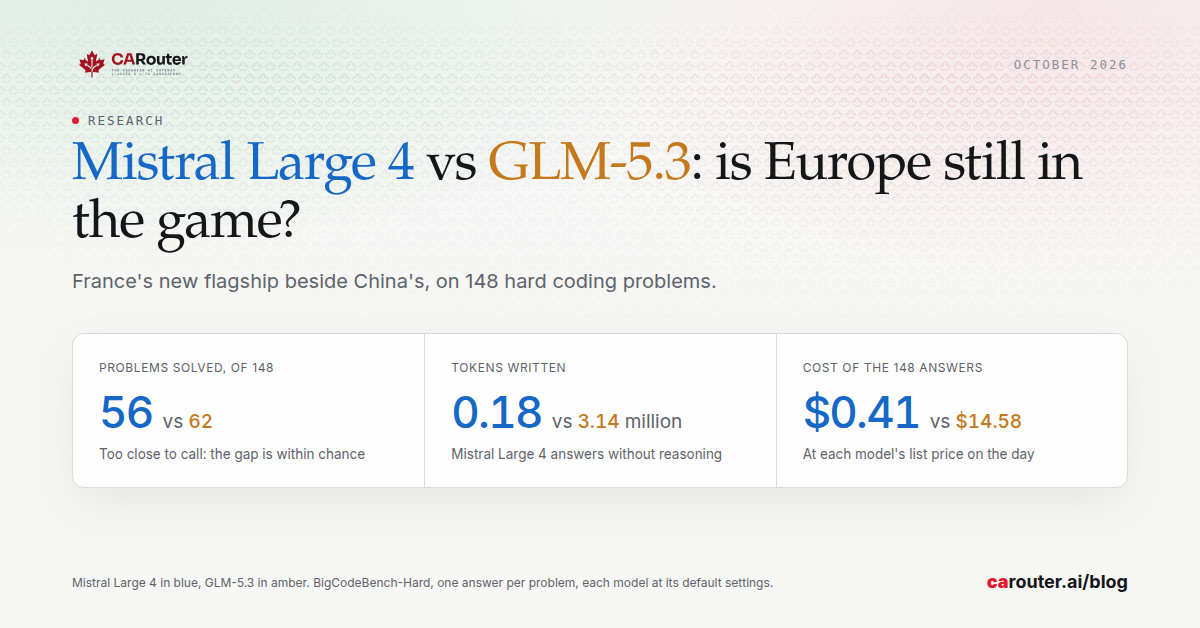
Read the articleMistral Large 4 vs GLM-5.3: is Europe still in the game?
Mistral's new flagship solved 56 of 148 hard coding problems against 62 for GLM-5.3, China's flagship. The gap is within chance, and…
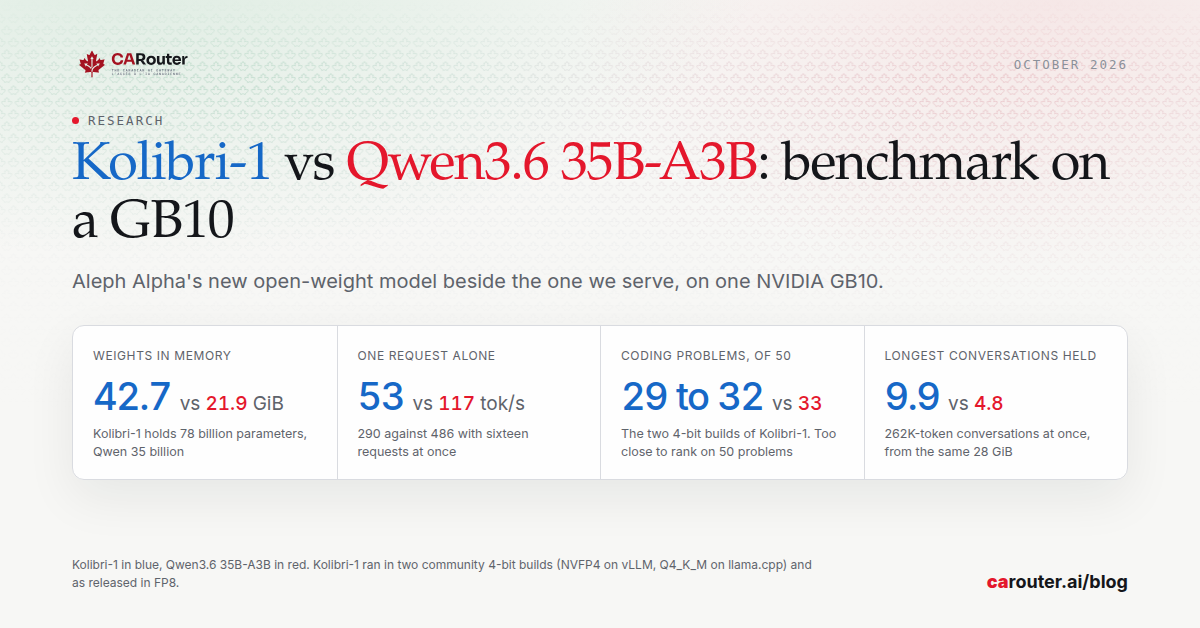
Read the articleKolibri-1 vs Qwen3.6 35B-A3B: benchmark on a GB10
Aleph Alpha's new open-weight Kolibri-1 reads about 3 billion parameters per token, like the Qwen3.6 35B-A3B we serve. On a GB10 at 4 bits…
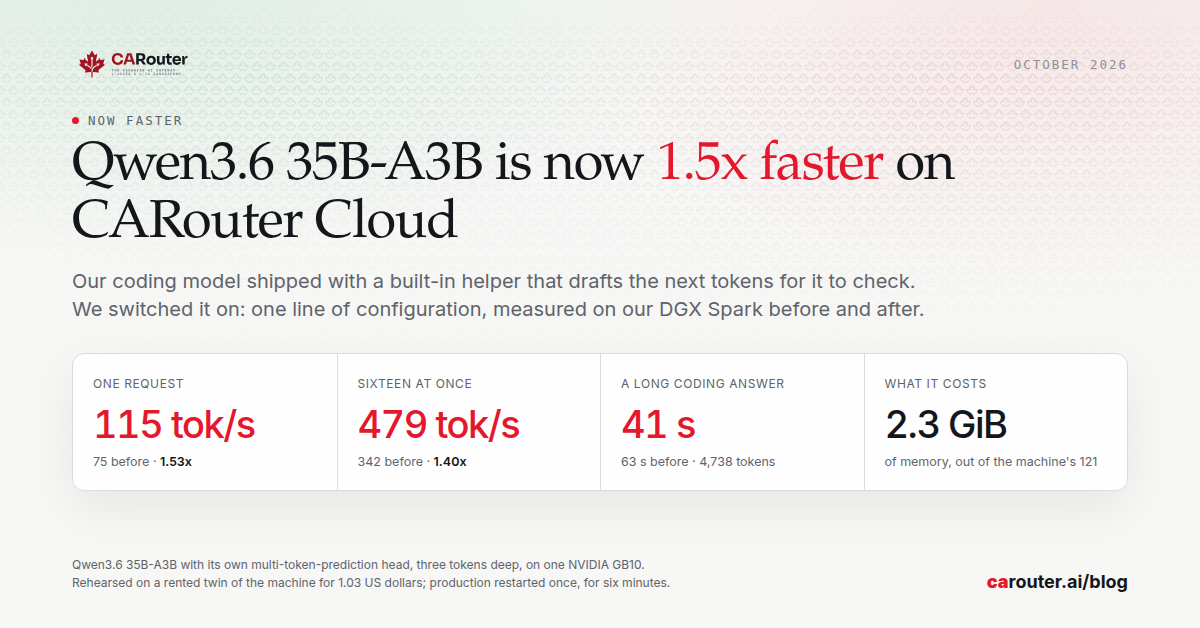
Read the articleQwen3.6 35B-A3B is now 1.5x faster on CARouter Cloud
Our coding model shipped with a built-in helper that drafts the next tokens for the main model to check. We switched it on with one line of…
Read the articlePricing that makes sense
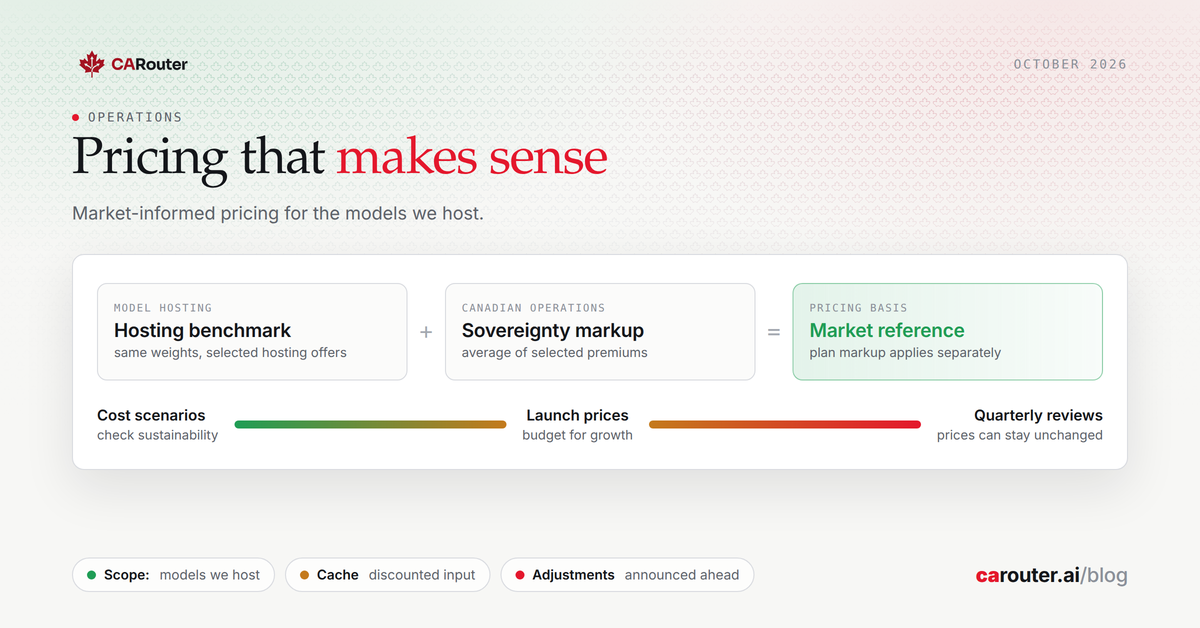
Our pricing policy for models we host ourselves: a market reference adjusted for sovereignty, explicit cost assumptions and room to invest…
Read the articleClef and Strands Decider vs Kev-4B: benchmark on a GB10
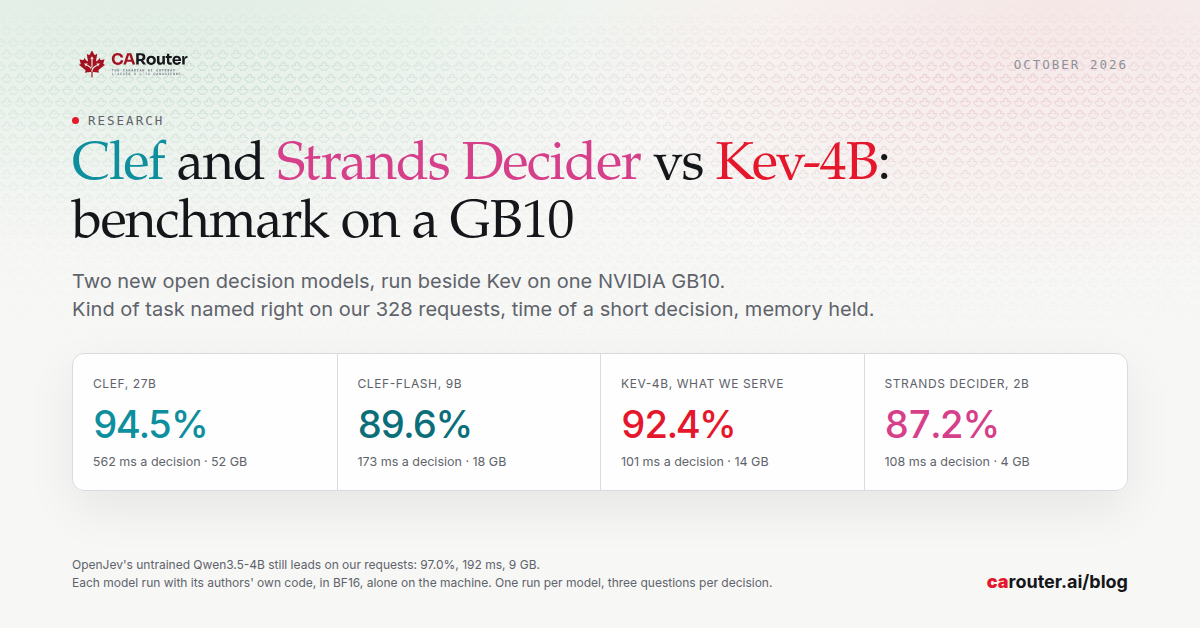
Cloudflare's Clef and Strands Labs' Strands Decider are two new open decision models. On a GB10, Clef named the kind of task right on 94.5%…
Read the articleOpenJev vs Kev-4B: benchmark on multiple CPU/GPU hardware
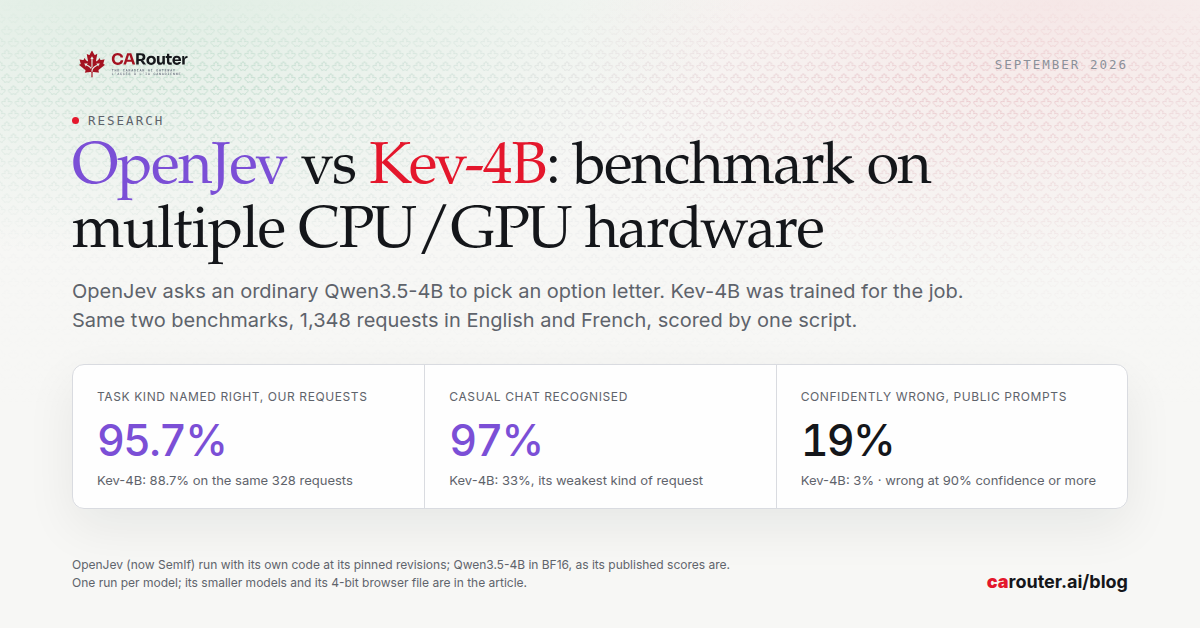
OpenJev asks an ordinary Qwen3.5-4B to pick an option letter, with no training for the job. On the two benchmarks we used to choose Kev-4B,…
Read the articleJev-class model Kev is available on CARouter (+ benchmarks)
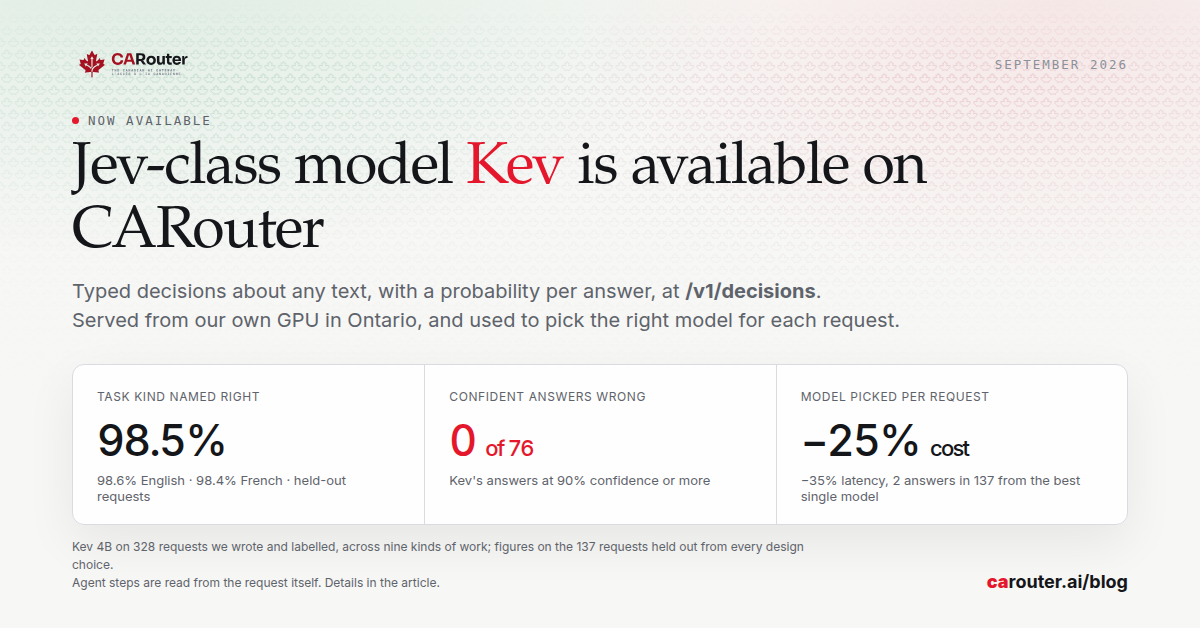
Kev 4B, an open decision model that answers typed questions the way TypeSafe's Jev does, is now callable at /v1/decisions from our own…
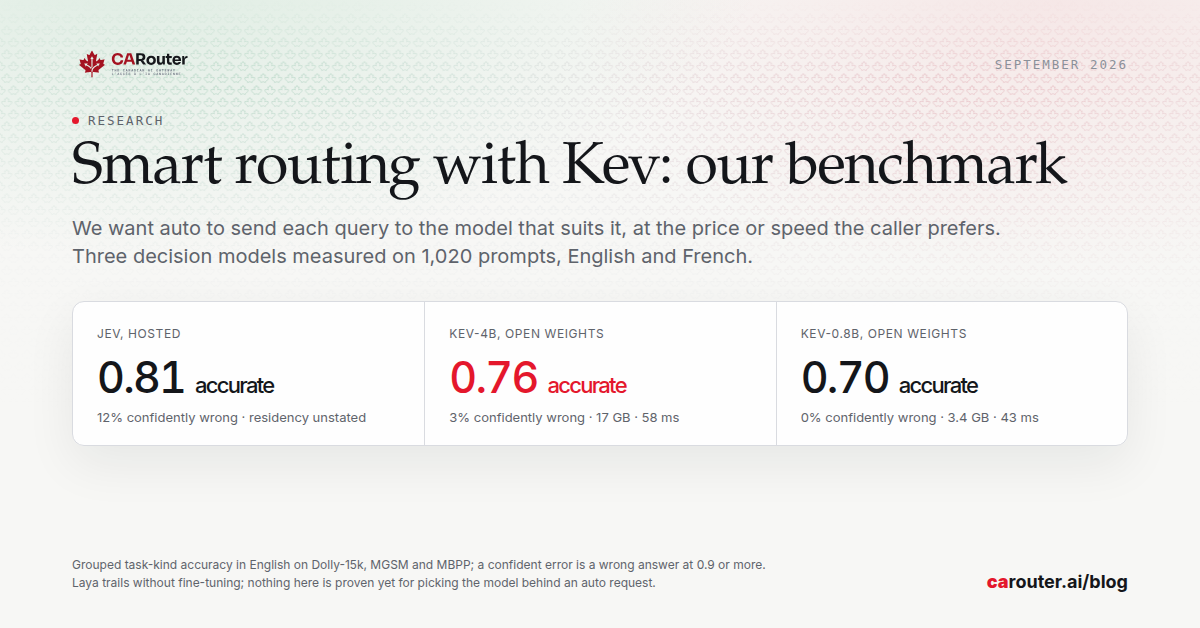
Read the articleSmart routing with Kev: our benchmark
A request to CARouter could name no model at all and still land on the right one, at the price or speed you prefer. We tested three…
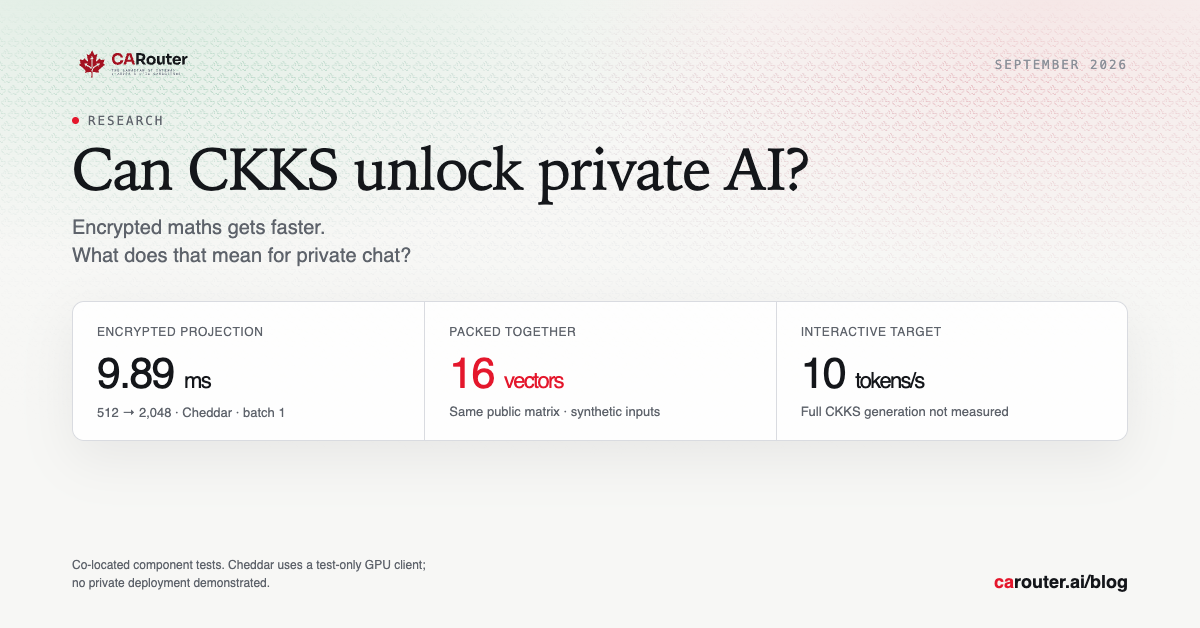
Read the articleCan CKKS unlock private AI?
We tested current CKKS GPU libraries at Qwen model dimensions. Matrix speed and batching improved; a complete private chat service remains…
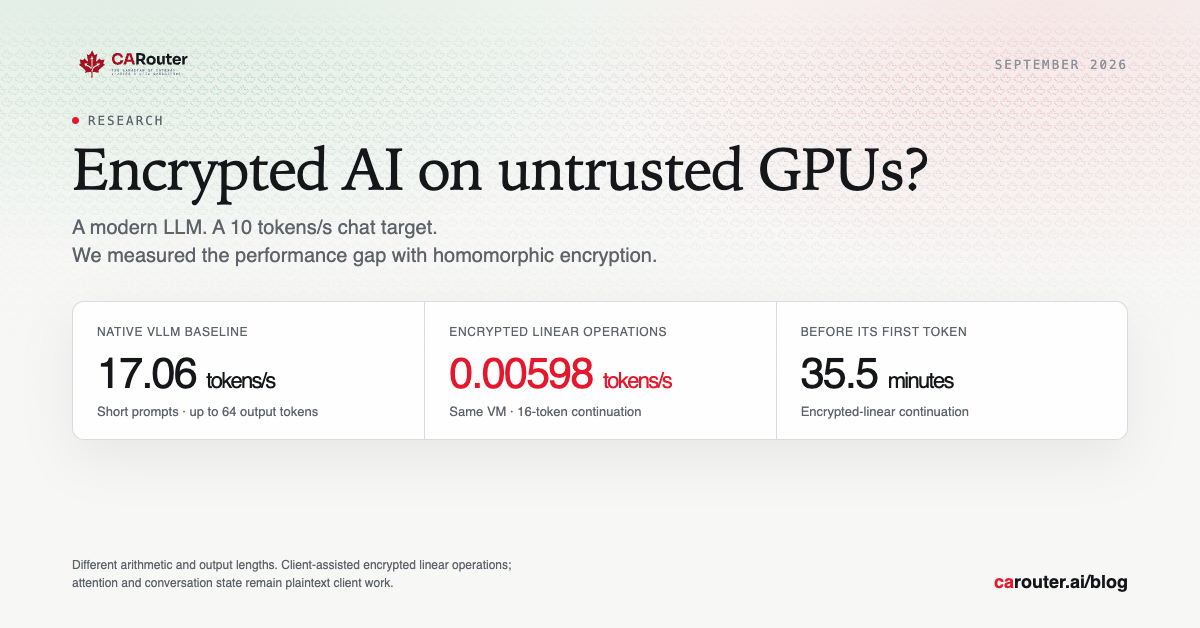
Read the articleAnswering the sovereignty concern and GPU shortage with homomorphic LLM inference
We tested client-assisted homomorphic inference from GPT-2 to Qwen3.6-35B-A3B, including a separate trusted CPU client. Methodology,…
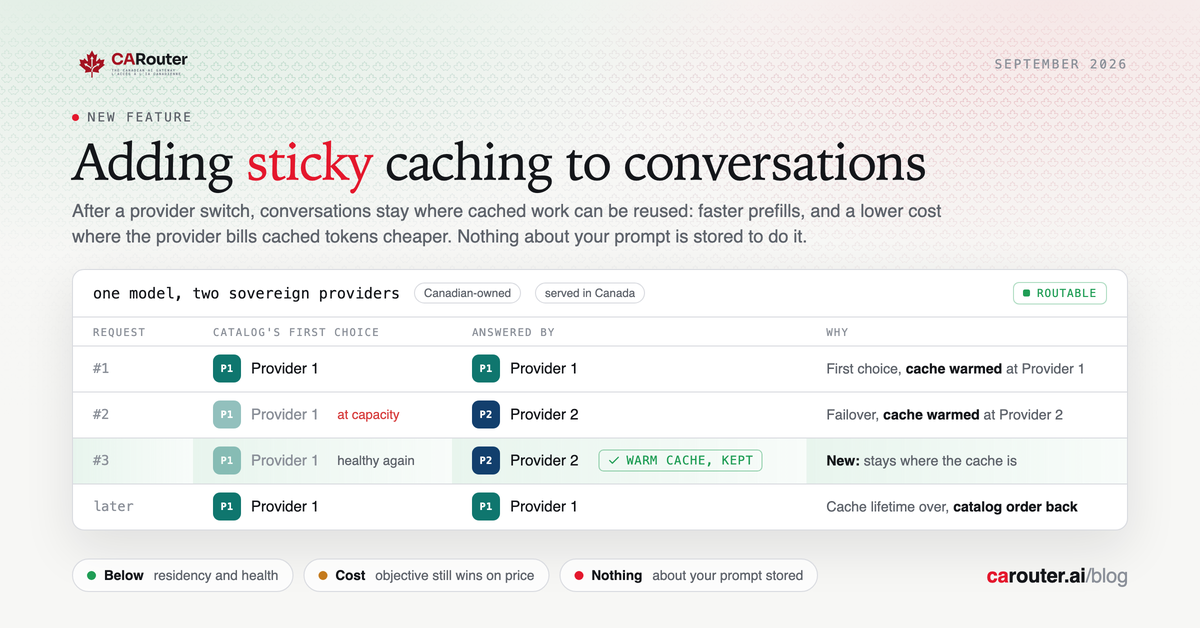
Read the articleAdding sticky caching to improve cost and speed
Repeated instructions can cost less and process faster when an AI provider can reuse earlier work. Cache affinity helps preserve that…
Read the articleGreener tokens: the carbon footprint of every model, before you pick one
Every offer on our documentation page now shows an estimate of the carbon emitted to serve a million tokens, coloured by the grid it runs…
Read the articleCARouter is in Denvr AI Ascend: cloud credits for benchmarks on Canadian hardware
CARouter is in Denvr AI Ascend, the startup program of a Canadian-owned cloud running its own GPUs in Calgary. The credits buy measurements…
Read the articlePartnering with Augure: two Canadian-trained models, served only in Canada
Rosedale One and Tofino 3 are live on the gateway. Served in Canada or refused, never failed over abroad, prompts kept by nobody once…
Read the articleQwen3.8-Flash-Next on CARouter's DGX Spark: better answers, for 10 times the wait
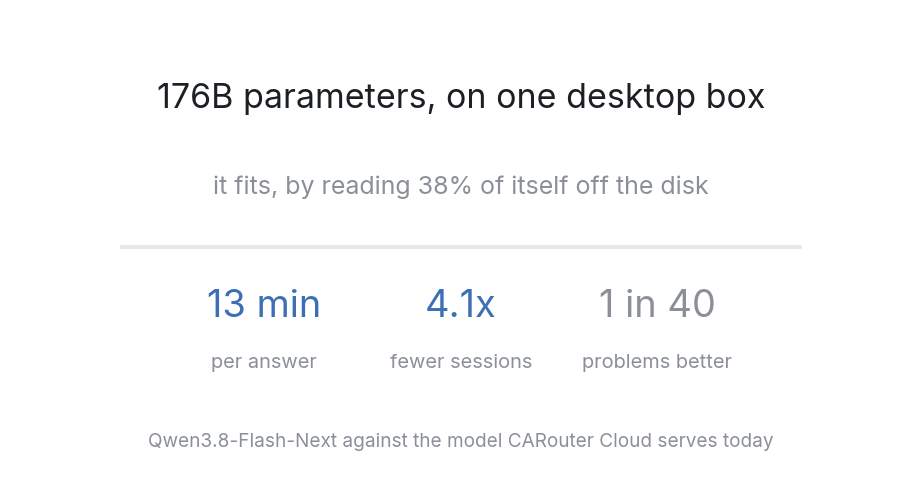
Qwen's Qwen4 architecture preview tops the coding leaderboards, and its smallest servable build is 125.9 GiB against a machine that has…
Read the articleWhy we now serve Qwen3.6 35B-A3B instead of Qwen3.8 27B
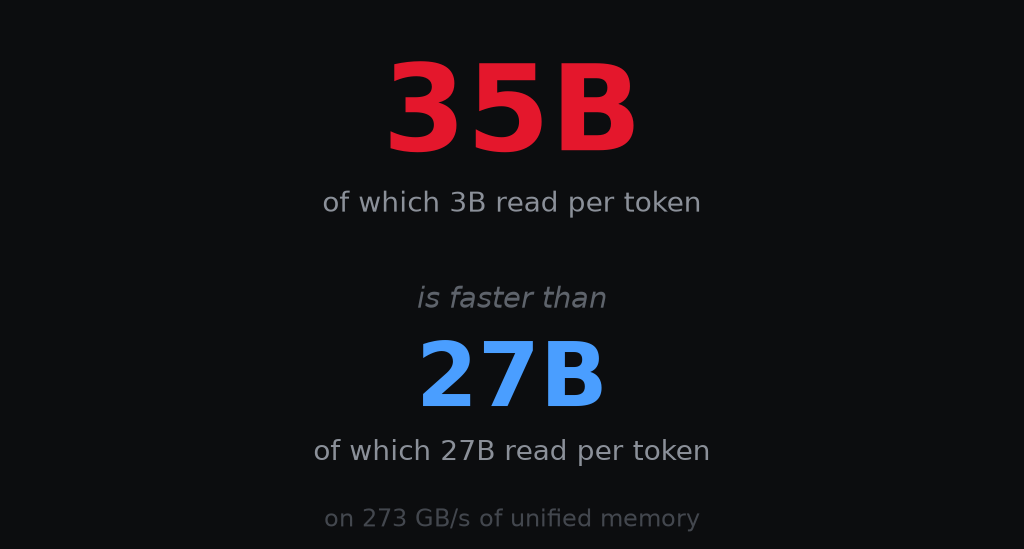
A dense 27B has to read all 23.4 GB of itself to write one token, which on our DGX Spark caps it at about 12 tokens a second and turned a…
Read the articleTuning speculative decoding on CARouter's DGX Spark: two thirds faster coding answers, same hardware
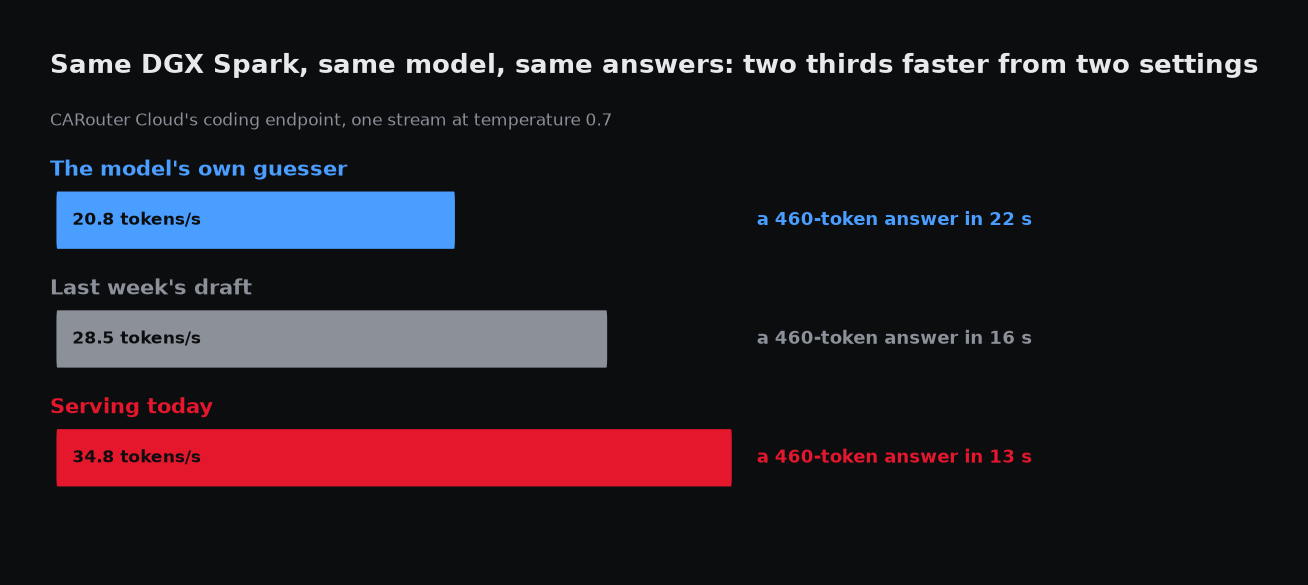
Speculative decoding has a small draft model guess ahead so the big one can check several tokens at once. Which guesses it makes, and how…
Read the articleMTP vs DFlash2 on CARouter's DGX Spark: 35% more tokens per step, not a faster step
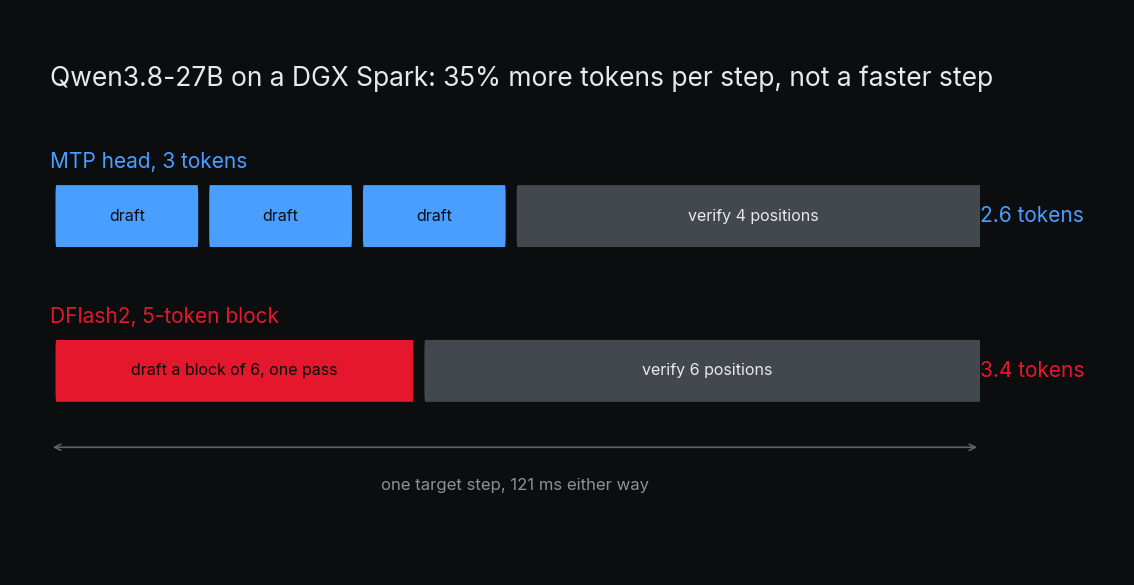
A newsletter promised 3× from speculative decoding the morning vLLM 0.28.0 shipped the drafter Qwen3.8-27B was missing. We checked the…
Read the articleLaguna S 2.1 vs Qwen3.8-27B on CARouter's DGX Spark: speed lost to memory
Poolside's Laguna S 2.1 decodes two and a half times faster than Qwen3.8-27B on our 128 GB DGX Spark. We shipped Qwen anyway: it fits in a…
Read the article